CLOUDOPS
Keep Your Cloud Reliable, Visible & Ready
Keep Your Cloud Reliable, Visible & Ready
We build the operational practices, automation, and visibility that keep cloud workloads performing as your business changes.




- CloudOps Value
Turn Cloud Infrastructure Into a Reliable Operation
We connect technology, processes, and ownership so your teams can operate the cloud with clarity.
Greater Service Reliability
 Greater Service Reliability
Monitor workload health and strengthen the processes supporting availability and recovery.
Faster Incident Response
Clear Operational Visibility
 Clear Operational Visibility
Bring infrastructure, application, security, and performance signals into one operational view.
Proactive Capacity Planning
- Capabilities
Everything Required to Operate the Cloud
We establish the controls and workflows that support reliable cloud services day after day.
Monitoring & Observability
Connect metrics, logs, traces, dashboards, alerts, and service health across cloud environments. Gain total real-time visibility into your infrastructure health, empowering your lean IT team to detect and resolve potential bottlenecks before they ever impact your customers.
Incident & Problem Management
Define detection, triage, escalation, communication, resolution, and post-incident review processes. Minimize costly downtime and protect your brand reputation with rapid, structured response frameworks designed specifically to keep your fast-growing startup online.
Reliability Management
Establish service indicators, service objectives, availability targets, and reliability reviews. Guarantee consistent, enterprise-grade uptime for your digital products, building immediate trust with your growing user base while controlling operational overhead.
Capacity & Performance Management
Monitor resource utilization, workload demand, response times, throughput, and scaling requirements. Ensure your platforms remain lightning-fast and highly cost-effective, seamlessly adapting to sudden traffic spikes as your business aggressively scales.
Backup & Recovery Operations
Manage backup policies, retention, restoration testing, and recovery procedures. Safeguard your company's most critical proprietary data with rock-solid continuity plans, ensuring instant restoration and absolute peace of mind during unexpected disruptions.
Configuration & Change Control
Track cloud configurations, operational changes, approvals, ownership, and configuration drift. Maintain absolute order over your scaling environment, allowing your agile engineering team to deploy necessary operational updates without introducing destabilizing risks.
Patch & Maintenance Management
Coordinate operating system updates, platform maintenance, testing, and maintenance windows. Eliminate hidden security vulnerabilities seamlessly behind the scenes, keeping your foundational systems fully compliant and protected without interrupting daily business workflows.
Cloud Operations Automation
Automate common responses, health checks, maintenance tasks, scaling actions, and recovery workflows. Multiply your workforce's daily capacity by replacing repetitive manual upkeep with intelligent, self-healing loops, freeing your core talent for high-impact strategic initiatives.
- Operational Visibility
See the Complete Cloud Operation
We connect the signals your teams need to understand service health and make informed decisions.
Infrastructure Health
We deliver deep visibility into your compute, containers, networks, storage, databases, and managed services. Continuous monitoring ensures you catch resource bottlenecks early and maintain rock-solid reliability across every infrastructure layer.
Application Performance
We track critical availability, latency, error rates, throughput, and key user journeys in real time. This granular observability empowers your engineering team to resolve performance degradation before it impacts end users.
Security Signals
We centralize access events, configuration findings, vulnerabilities, and suspicious activity logs. Proactive threat detection and signal correlation protect your cloud environment from breaches and streamline compliance audits.
Service-Level Performance
We measure actual operational performance against defined service indicators and strict reliability objectives. Aligning monitoring with SLAs ensures your systems consistently meet business commitments and customer expectations.
Business-Critical Workloads
We prioritize monitoring around the specific systems, transactions, and user experiences that matter most to your revenue. Focusing observability on high-impact workloads ensures rapid incident response where it counts.
Operational Reporting
We deliver clear, actionable reporting covering service health, incidents, capacity trends, and ongoing improvements. Transparent data empowers technical teams and leadership to make informed, strategic decisions.
- Operating Model
Clear Ownership Behind Every Cloud Service
We define how teams, tools, and processes work together across daily cloud operations.
Roles & Responsibilities
Service Levels
Runbooks & Response Plans
Alert & Escalation Design
Operational Reviews
Knowledge & Documentation


- THE CLOUDOPS TEST
When Do You Need a CloudOps Engagement?
CloudOps earns its place when a cloud environment is in production and operations are still reactive or invisible.
A good fit
- Users discover production incidents before your internal teams
- On-call processes are chaotic and lack standardized runbooks
- Monitoring tools are deployed but lack operational discipline
- Critical disaster recovery procedures remain untested
- Cloud costs are escalating without clear visibility or ownership
A different approach
- The foundational cloud environment is not yet built
- You require a fully managed team to run operations for you
- You strictly need software delivery and deployment automation
From Cloud Visibility to Operational Excellence
Six steps from reviewing your current operation to continuous improvement.
Assess Operations
We review your workloads, monitoring, incidents, responsibilities, processes, tools, and service expectations.
Define the Operating Model
We establish ownership, service levels, escalation paths, maintenance practices, and operational priorities.
Connect Observability
We implement monitoring, logging, tracing, dashboards, alerts, and service-level reporting.
Automate the Response
We create runbooks and automation for recurring events, maintenance, scaling, and recovery.
Validate Readiness
We test alerts, escalation procedures, backup restoration, incident response, and recovery workflows.
Improve Continuously
We use service data, operational reviews, and incident learnings to guide ongoing improvements.
- Operational Assurance
Built for Reliability, Resilience & Control
Cloud operations remain aligned with your performance, security, and business requirements.
Operational Readiness
Every workload enters live production backed by health tracking, clear system guides, named owners, support coverage, and recovery plans. Setting up these operational foundations before launch prevents day-one surprises and ensures your internal team can manage new releases with total confidence.
Incident Preparedness
Clear severity levels, step-by-step response playbooks, direct communication channels, and assigned escalation owners guide your team through any disruption. Having a structured game plan removes panic during outages, cuts resolution times, and keeps leadership and customers informed.
Recovery Validation
We regularly test your backup systems and restoration workflows against strict recovery time and data protection targets. Proving that your safety nets work in real life guarantees your business can bounce back quickly from hardware failures or cloud outages without losing critical records.
Security Operations Alignment
Daily cloud management connects directly with user access rules, threat monitoring, vulnerability scans, and security response workflows. Unifying daily operations with strict protection keeps your platform safe from outside attacks and maintains compliance with North American and European privacy laws.
Controlled Change
Every infrastructure update follows a documented cycle of peer review, staging tests, manager sign-off, and instant rollback planning. Putting firm guardrails around system modifications stops human error from breaking active applications or slowing down daily revenue operations.
Continuous Learning
After any operational hiccup, we run blameless reviews to find the root cause, apply permanent fixes, and build new automation that blocks repeat issues. Turning past incidents into smarter system rules makes your cloud environment stronger, faster, and cheaper to run over time.
- Validated Execution
Cloud Operations in Practice
See how we improve cloud visibility, reliability, response, and operational control across production environments.
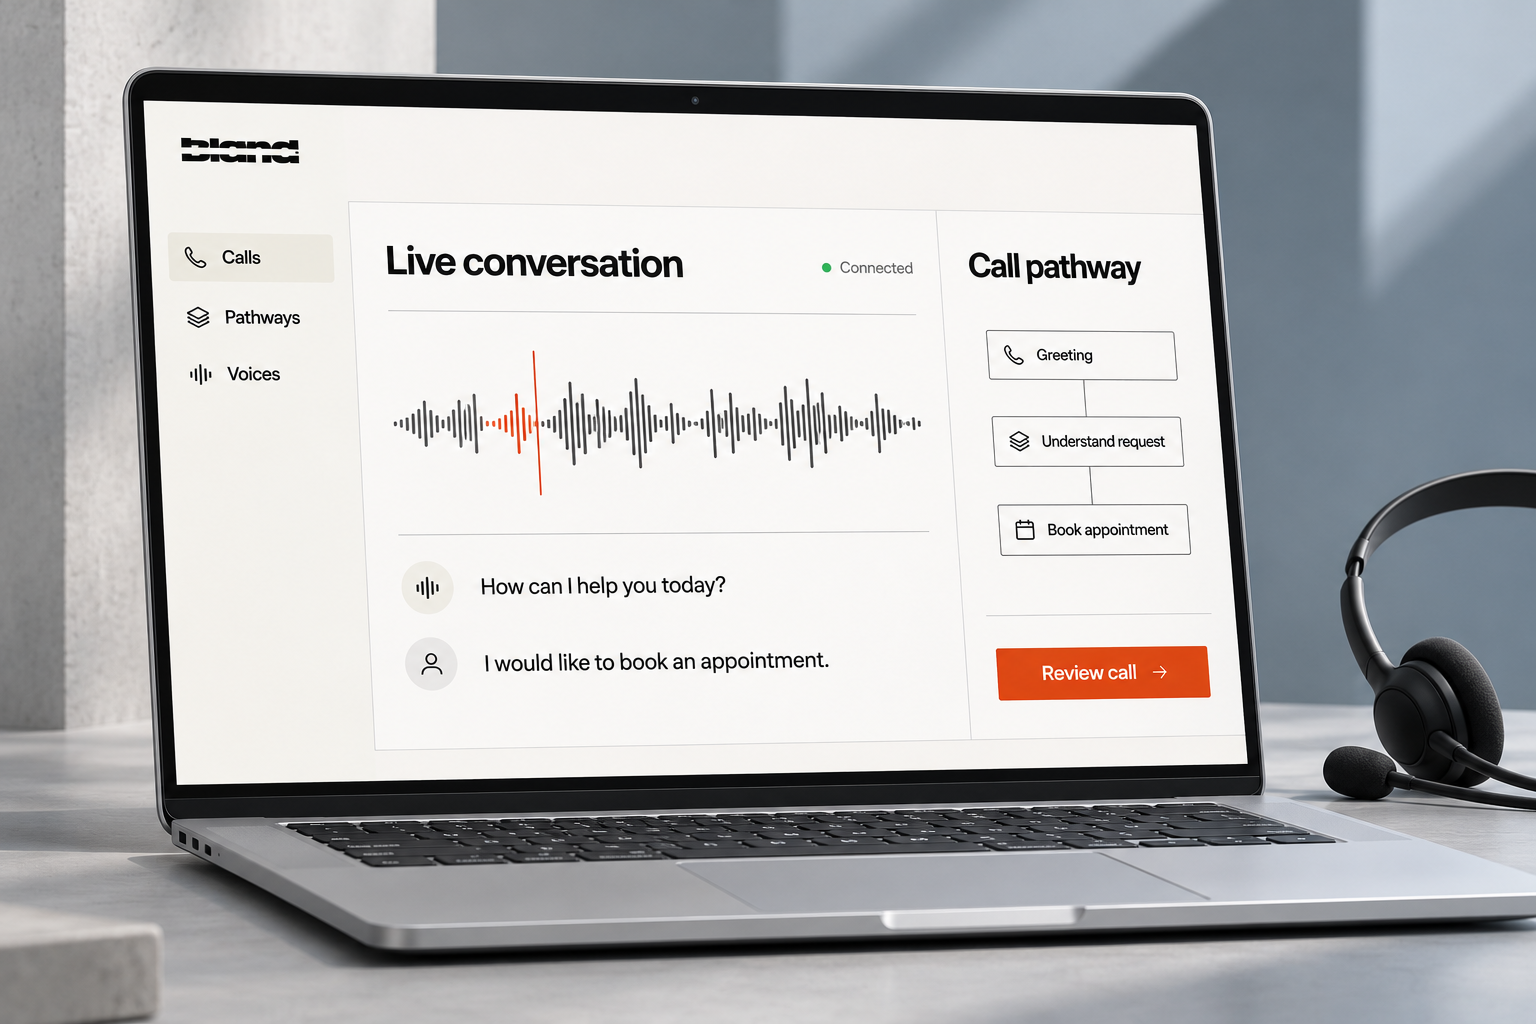
Bland AI: Bringing automation to customer calls
Conversational AI, connected to a production delivery workflow.
AI Agent ● AngularJS ● AWS ● Node.js
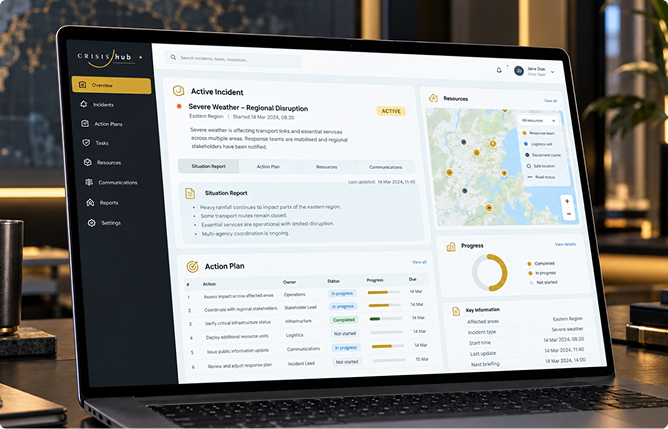
CrisisHub: Turning crisis plans into coordinated action
From planning the response to tracking its execution.
AngularJS ● AWS ● Node.js ● PostgreSQL
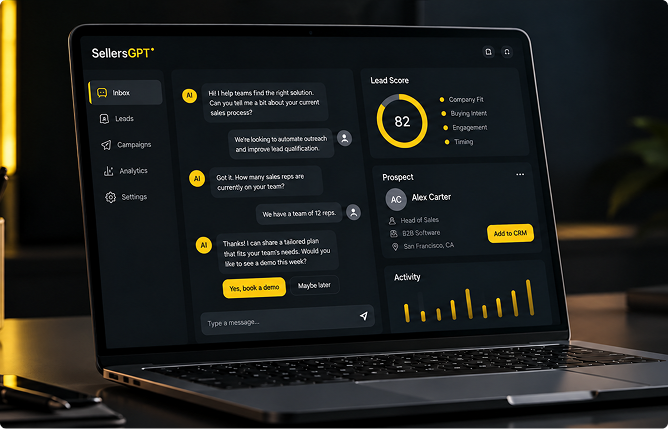
SellersGPT: Turning sales conversations into qualified opportunities
Automated lead qualification through natural conversations
AI Agent ● RAG ● SaaS Development
FAQ
What is CloudOps?
CloudOps combines the people, processes, tools, and automation required to operate cloud infrastructure and workloads reliably.
How is CloudOps different from DevOps?
CloudOps focuses on cloud health, reliability, incidents, capacity, and operations. DevOps focuses on software delivery, testing, deployment, and collaboration between development and operations.
Can you work with our existing monitoring tools?
In most cases, yes. We work with platforms such as CloudWatch, Azure Monitor, Google Cloud Operations, Grafana, Prometheus, Datadog, and New Relic, and build on what is already in place rather than replacing it.
Do you support hybrid and multi-cloud environments?
In most cases, yes. We establish monitoring and operating practices across public cloud, private cloud, and on-premises infrastructure, with unified visibility where possible.
How is this different from Managed Cloud Services?
CloudOps establishes and improves your operational capability. Managed Cloud Services can provide ongoing responsibility for running that capability as an extension of your team.
Where should we start if our monitoring is minimal?
With an operational assessment. We review what exists, identify the gaps creating the most risk, and improve the highest-priority areas first.
How is CloudOps work priced?
An initial assessment and observability setup is typically fixed price. Ongoing operational support runs through a Dedicated Team or Managed Cloud Services arrangement. See our engagement models for the full range.
Who owns the runbooks, automation, and configurations?
You do. The runbooks, automation scripts, dashboards, configurations, and documentation created for your environment belong to you, as set out in your agreement.
- Related Services
CloudOps Across the Stack
Explore the services that build on and connect to cloud operations.