MLOPS & AI INFRASTRUCTURE
Move Models Into Reliable Production
Move Models Into Reliable Production
We build the pipelines, infrastructure, and controls that keep AI systems deployable, observable, and cost-efficient as you scale.




- Production Needs
What Production AI Requires
A model that works in testing still needs the operations behind it to stay reliable in production.
Repeatable Deployment
 Repeatable Deployment
Move models between development, testing, and production through controlled pipelines.
Visible Performance
Reproducible Results
 Reproducible Results
Track the data, code, parameters, and environments behind every model version.
Scalable Infrastructure
- Capabilities
Everything Production AI Runs On
From pipelines and serving to monitoring and GPU infrastructure, we build the platform your models run on.
ML Pipelines
Automated workflows for data preparation, training, evaluation, approval, and deployment. Accelerate your time-to-market by replacing manual processes with reliable, repeatable loops that keep your engineering team focused on innovation rather than maintenance.
Model Deployment
Batch, real-time, edge, API-based, and containerized model serving. Launch your intelligent features flawlessly across any environment, ensuring your customers experience low-latency, high-performance interactions as your user base rapidly grows.
Model Registry & Versioning
Centralized tracking for models, experiments, metadata, approvals, and releases. Maintain absolute order over your AI assets, allowing your data scientists to collaborate seamlessly and roll back safely without operational chaos.
Monitoring & Drift Detection
Continuous visibility into accuracy, data changes, latency, errors, and resource usage. Protect your brand reputation by instantly detecting when models degrade, ensuring your products always deliver accurate and trustworthy results to your users.
Cloud AI Infrastructure
Secure AI environments across AWS, Microsoft Azure, Google Cloud, and hybrid systems. Build on a flexible, cost-optimized foundation that scales effortlessly with your business's growth while avoiding strict vendor lock-in.
CI/CD for Machine Learning
Automated testing and delivery for model code, pipelines, infrastructure, and configurations. Ship updates with complete confidence, bridging the gap between data science and operations to deploy rapid, error-free product enhancements.
GPU Infrastructure
Scalable compute environments for model training and high-performance inference. Maximize your processing power while tightly controlling cloud costs, giving your ambitious team the resources they need to train sophisticated models efficiently.
LLMOps & AI Application Ops
Evaluation, prompt and model versioning, tracing, guardrails, and cost control for LLM and agent applications. Safely manage complex generative AI features in production, ensuring predictable behavior and strict budget adherence as usage spikes.
Private & On-Premise AI
Deploy models in your own virtual private cloud (VPC) or on-premise infrastructure, ensuring sensitive data never leaves your boundary. Meet strict compliance requirements and build immediate trust with your clients by retaining absolute control over proprietary information.
- Model Lifecycle
One Controlled Model Lifecycle
Every model moves through the same repeatable, traceable path from experiment to production.
Experiment
We meticulously track your datasets, feature engineering, and model configurations. This centralized approach guarantees every experiment remains fully reproducible, transparent, and ready for rigorous technical validation.
Validate
We rigorously test model quality, security, and performance against strict operational benchmarks. This comprehensive validation ensures your AI remains reliable, compliant, and ready for live production.
Register
We securely store approved models with complete version history and data lineage. This centralized registry ensures strict governance, rapid rollbacks, and absolute traceability for regulatory compliance.
Deploy
We release models into production through automated, highly repeatable CI/CD pipelines. This streamlined deployment eliminates manual bottlenecks, ensuring new intelligent capabilities reach your users flawlessly.
Monitor
We continuously measure model behavior, system health, and real-time data drift. Live tracking dashboards provide instant alerts, ensuring your infrastructure stays reliable and computing costs remain predictable.
Improve
We leverage live production data to retrain, compare, and approve stronger algorithms. This continuous improvement loop guarantees your AI systems adapt seamlessly to shifting market conditions.


- THE MLOPS TEST
How Much MLOps Do You Need?
The optimal infrastructure depends on your model volume, deployment frequency, and compliance requirements.
A good fit
- AI models are in active production or approaching launch
- Manual release processes are slow, inconsistent, or error-prone
- Multiple models or cross-functional teams share the same platform
- Strict audit, security, and enterprise uptime requirements apply
A different approach
- Running a single model at low volume where managed cloud services suffice
- Foundational models are not yet developed or tested
- Infrastructure needs are highly fluid and likely to change rapidly
Built Around Your Models, Teams & Cloud
Five steps from assessment to an operating, monitored platform.
Assess
We review your models, workflows, infrastructure, deployment process, and operational requirements, and recommend the right level of tooling.
Architect
We design the platform, environments, pipelines, access controls, and monitoring approach.
Automate
We implement repeatable testing, training, deployment, and infrastructure workflows.
Operationalize
We establish monitoring, alerts, model ownership, approval stages, and recovery procedures.
Optimize
We improve performance, reliability, release speed, and infrastructure cost using production data.
- Reliability & Governance
Reliability, Security & Governance
We build in the controls that keep AI systems secure, traceable, and dependable. Compliance remains a shared responsibility with your organization.
Environment Isolation
Development, testing, and production environments remain strictly separated behind secure firewalls and access gates. Keeping experimental sandboxes away from live customer servers prevents accidental data leaks and ensures new code runs safely before touching live business workflows.
Model Traceability
Every software release links directly to its underlying code version, training datasets, configuration settings, test results, and manager sign-off history. Providing a complete audit trail makes it fast and simple to satisfy regulatory reviews, internal security checks, and client compliance questionnaires.
Secure Access
Role-based permission rules protect your AI models, cloud infrastructure, sensitive databases, and deployment pipelines. Built to align directly with SOC 2, HIPAA, and GDPR standards, our setup ensures staff and external systems only touch the specific assets required for their daily tasks.
Release Controls
Automated quality checks, staging gates, instant rollback options, and phased rollouts reduce operational risk during updates. Engineering teams can push new AI capabilities to production smoothly while stopping bad builds from disrupting active users or core business operations.
Cost Monitoring
Real-time tracking dashboards give finance and engineering leaders clear visibility into compute power, cloud storage, inference calls, and overall token spend. Automated alerts and hard spending caps keep your monthly infrastructure bills predictable as platform traffic scales.
Recovery Planning
Automated backups, instant rollback pathways, system alerts, and failover routines keep your AI infrastructure running dependably around the clock. If a cloud server slows down or drops a connection, resilient architecture handles the issue quietly to protect uptime and maintain business continuity.
- Validated Execution
Production AI in Practice
See how we deploy, serve, and scale AI systems in production.
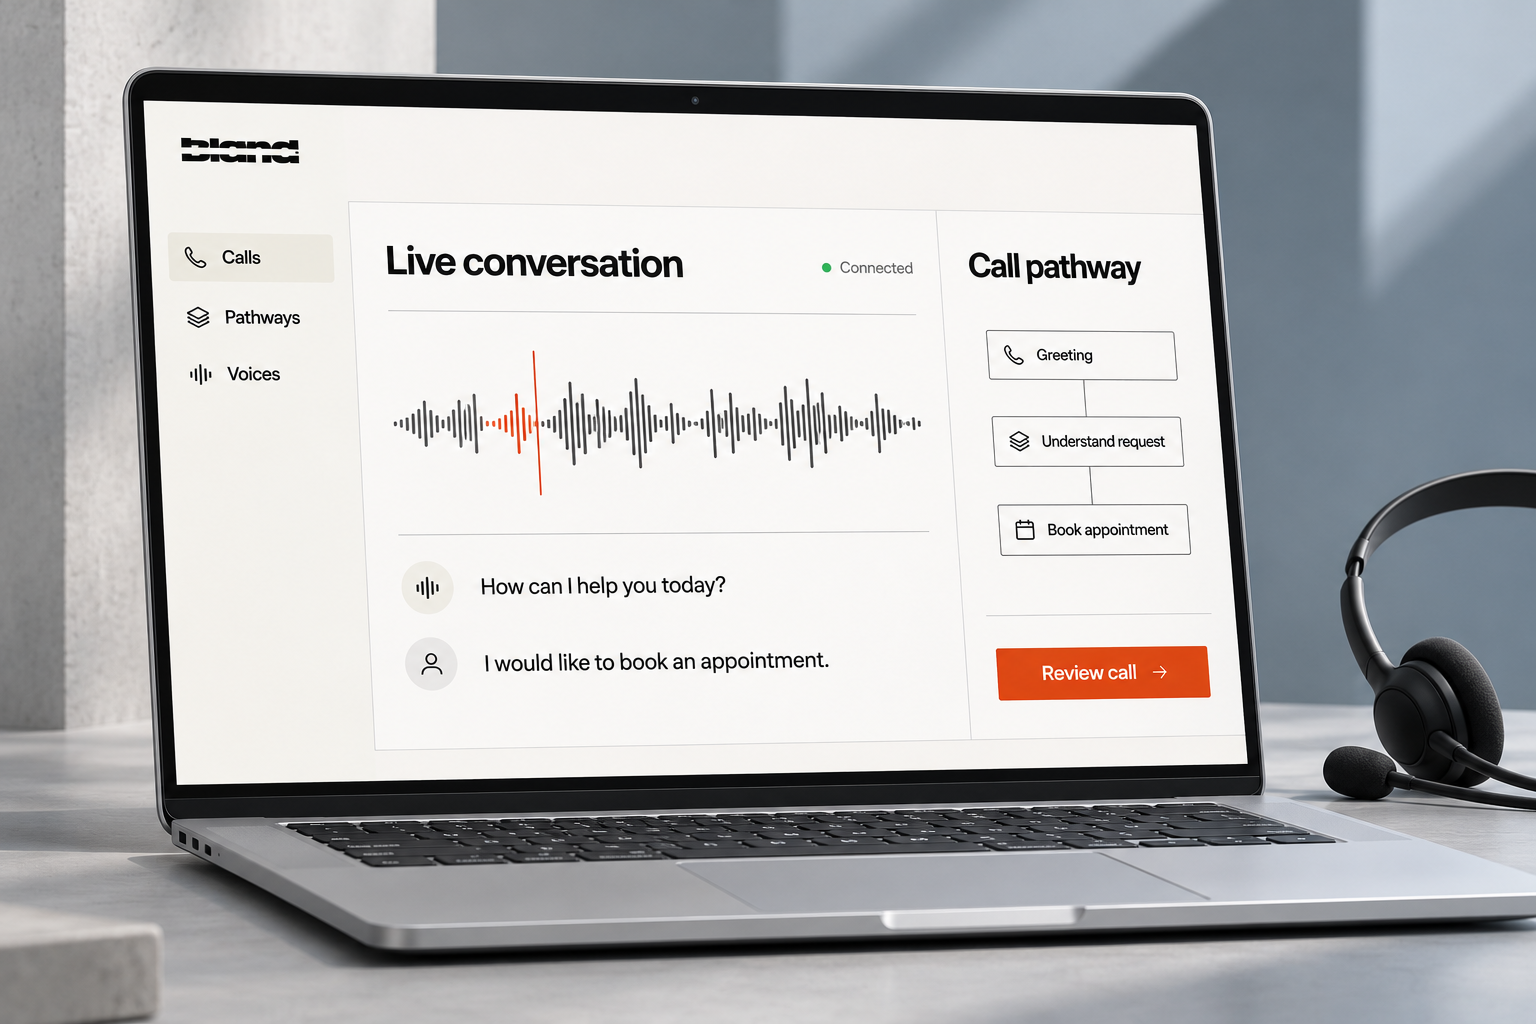
Bland AI: Bringing automation to customer calls
Conversational AI, connected to a production delivery workflow.
AI Agent ● AngularJS ● AWS ● Node.js
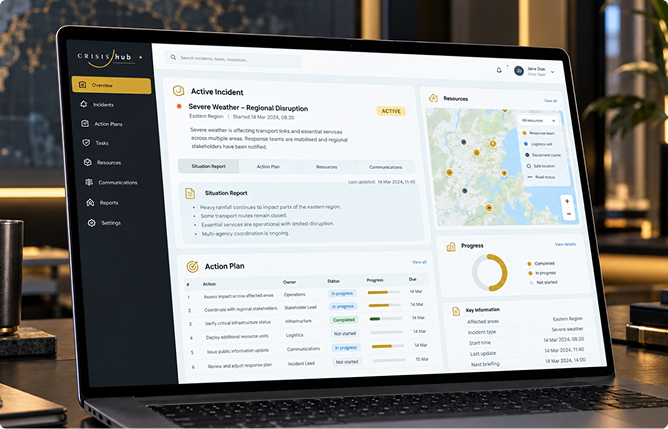
CrisisHub: Turning crisis plans into coordinated action
From planning the response to tracking its execution.
AngularJS ● AWS ● Node.js ● PostgreSQL
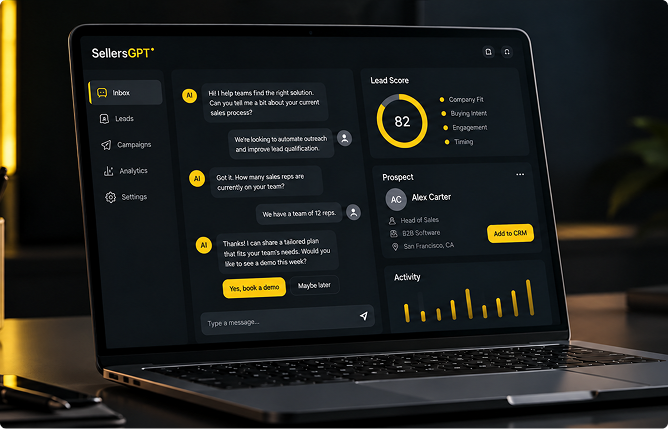
SellersGPT: Turning sales conversations into qualified opportunities
Automated lead qualification through natural conversations
AI Agent ● RAG ● SaaS Development
FAQ
What is MLOps?
MLOps combines machine learning, software engineering, data engineering, and operations to manage models throughout their production lifecycle.
Can you improve our existing ML deployment process?
In most cases, yes. We assess your current environment and strengthen its pipelines, monitoring, versioning, security, and release controls without replacing what already works.
Which cloud platforms and tools do you work with?
We work with AWS, Microsoft Azure, Google Cloud, private cloud, on-premise, and hybrid environments. We choose between managed services and open-source tooling based on your team, cost, and lock-in tolerance.
How do you detect model drift?
We monitor changes in input data, prediction patterns, model quality, and real-world outcomes against defined thresholds.
Can you support generative AI infrastructure?
Yes. We can implement LLMOps capabilities covering evaluation, prompt and model versioning, observability, usage, security, and cost.
Can you deploy AI privately or on-premise?
Yes. We deploy entirely within your own AWS, Azure, or GCP tenant (VPC), or on-premise GPU environments, so sensitive data stays strictly within your boundary.
How do you control AI infrastructure costs?
We monitor compute, storage, and inference usage, right-size infrastructure, and set alerts and limits so costs stay visible and predictable.
Who owns the pipelines and infrastructure code?
You do. The pipelines, infrastructure code, and documentation created for you belong to you, as set out in your agreement.
Can you run the platform for us, or train our team?
Both. We can operate and monitor the platform, or hand it over with documentation and training for your team.
- Related Services
Part of a Larger AI Stack
Explore the services that feed and use your platform.